Open source · MITRuns on your Cloudflare account

The AI growth team you don’t have to talk to.

Coding agents wait for your next prompt. GrowthHarness works like a senior SEO team: it researches before it writes, drops keywords you can’t win, and checks every claim against your site, in every language you sell in. It runs 24/7 and publishes on its own.

$npm run setup -- --local && npm run dev

Then walk away. It works the night shift.

Scroll to watch one night
05:30You’re offline

The classroom is the real console layout and figures. Numbers and the night are sample data.

GrowthHarness vs. a coding agent

A coding agent saves you time. GrowthHarness gives you back your attention.

A bright kitchen corner by a window. The owner cooks at the stove, back turned to the computer, while the team works on its screen.

With GrowthHarness

Off your mind.

You don’t even hand it a task. It reads your site, finds the searches worth winning, sets its own SEO strategy and decides what to write next, then writes, reviews and publishes it. Nothing waits on you, so there is nothing to keep in mind.

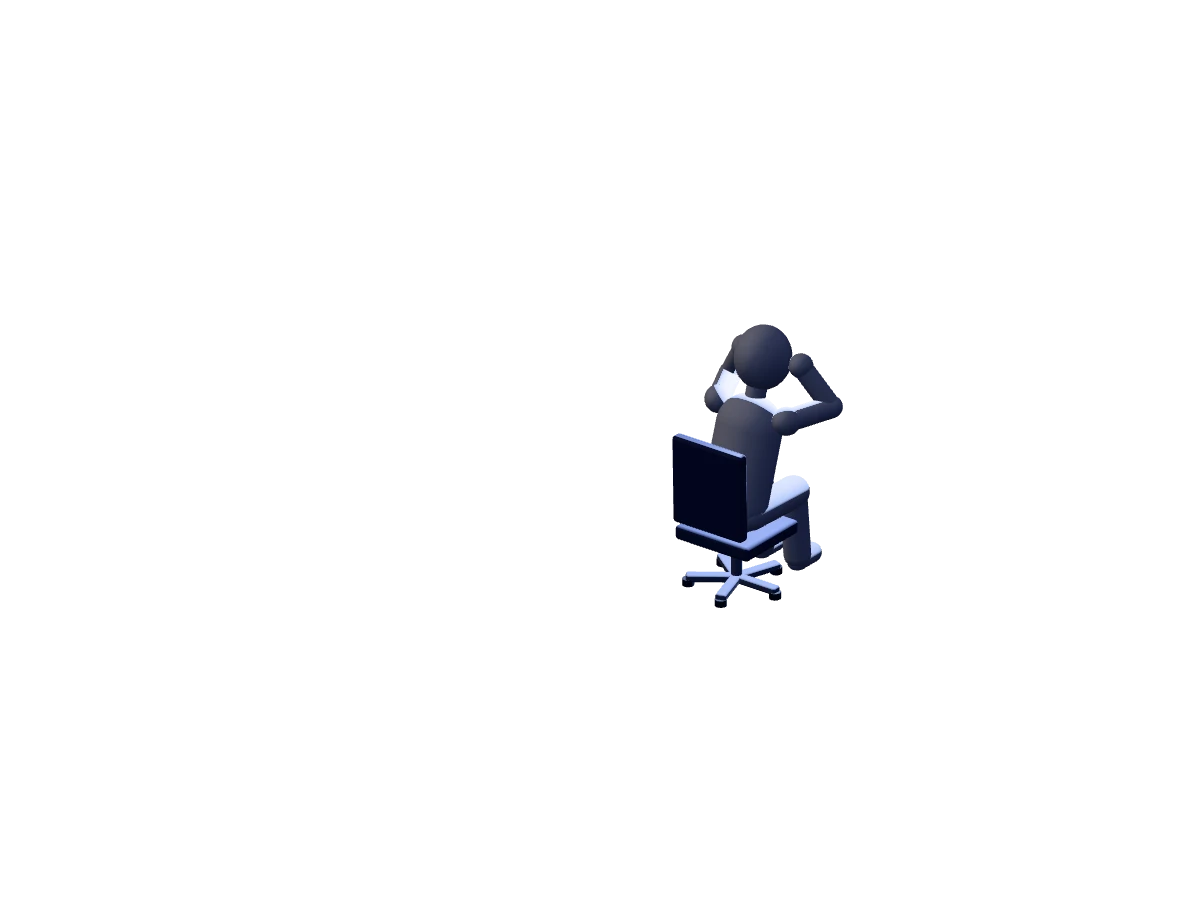
The same day with the blinds down. The owner sits at a desk lit only by a terminal, typing, waiting, then holding their head.

With a coding agent

Faster, and still on your mind.

Each answer arrives in seconds, then the next step waits for you: what to ask, what to check, what it missed. The work got faster. It never left your head.

The SEO chain, and who runs it

Most of SEO happens before the first sentence.

A senior SEO asks a different question at every step. Here each question has its own specialist, and each specialist hands over something you can read. A Leader makes the calls in between, so you never carry anything from one step to the next.

Sample output · Glossly is a fictional product · numbers are illustrative

Growth Leader

Hands each step to its owner, approves the topic group and decides what goes live. It asks you only when a business fact is missing, and your answer is information, not an approval.

  1. Strategist, with the Deep Researcher

    Strategy

    What should search do for this business, and where can it actually win?

    Studies who already owns these searches, then picks which topics to fight for and which to leave alone on purpose.

    It may also conclude that no new version is needed.

  2. SEO strategy + research notes
  3. Keyword Researcher

    Keywords

    What do people really type, and what are they trying to get done?

    Reads search intent and what Google shows today, and marks keywords already covered or overlapping your own pages.

    Volume and difficulty come from DataForSEO when connected. A missing number stays unknown, never zero.

  4. A keyword map, every word with a reason
  5. Topic Editor

    Topics

    What should we write now, and what should wait?

    Plans pages that support each other inside one subject. When the evidence is thin, it sends a research request back to the Strategist instead of filling a quota.

    Leader approves the group

  6. A topic group, or a request for research
  7. Editor-in-Chief and Writers

    Writing

    What does the reader need answered, and can we back up every claim?

    The Editor-in-Chief decides what each page covers. Writers work in parallel, up to 20 at once, and save the source sentence behind every fact.

    At most three internal links per language, only to published pages in the same language.

  8. A locked draft with its evidence
  9. Reviewer

    Review

    Would a careful editor let this go out under your name?

    Reads the exact draft without seeing how it was written. Checks reader value, whether each claim has evidence, coverage and links.

    A revision goes back to the same Writer.

  10. Pass, revise, or defer
  11. Growth Leader decides, the system executes

    Publish

    Can search engines and AI crawlers read it, and will the right person see the right language?

    The Leader reads the article and the review, then publishes or sends it back.

    The system adds language tags, canonical links and structured data from the real article, updates the sitemap and notifies search engines.

    Leader decides

  12. A live page on your own domain
  13. Learning Agent, off stage

    Results

    Did it work, and what should the next decision reuse?

    Weeks later, it scores each piece against real Search Console results, so the Leader can reuse what worked.

    Back to the Leader

Hosting included

It brings its own blog.

No CMS, no theme, no deploy pipeline. Point one subdomain at your Worker and the team publishes straight to it, at any hour.

DNS · glossly.example1 record
TypeNameTargetProxy
CNAMEbloggrowth-harness.you.workers.devProxied

This is the only step you take. The console shows the exact target and checks that the subdomain answers.

  • Pages, certificates and sitemap are served by your own Worker.
  • Every language on one domain, under /en/blog, /pt/blog, /de/blog, so they share its authority.
  • Looks like part of your brand. Your logo, picked up from your site automatically if you never set one, your name in each language, and a link back to your homepage.
  • Search Console stays yours. Sign in with Google once. No TXT record, no submitting URLs by hand.
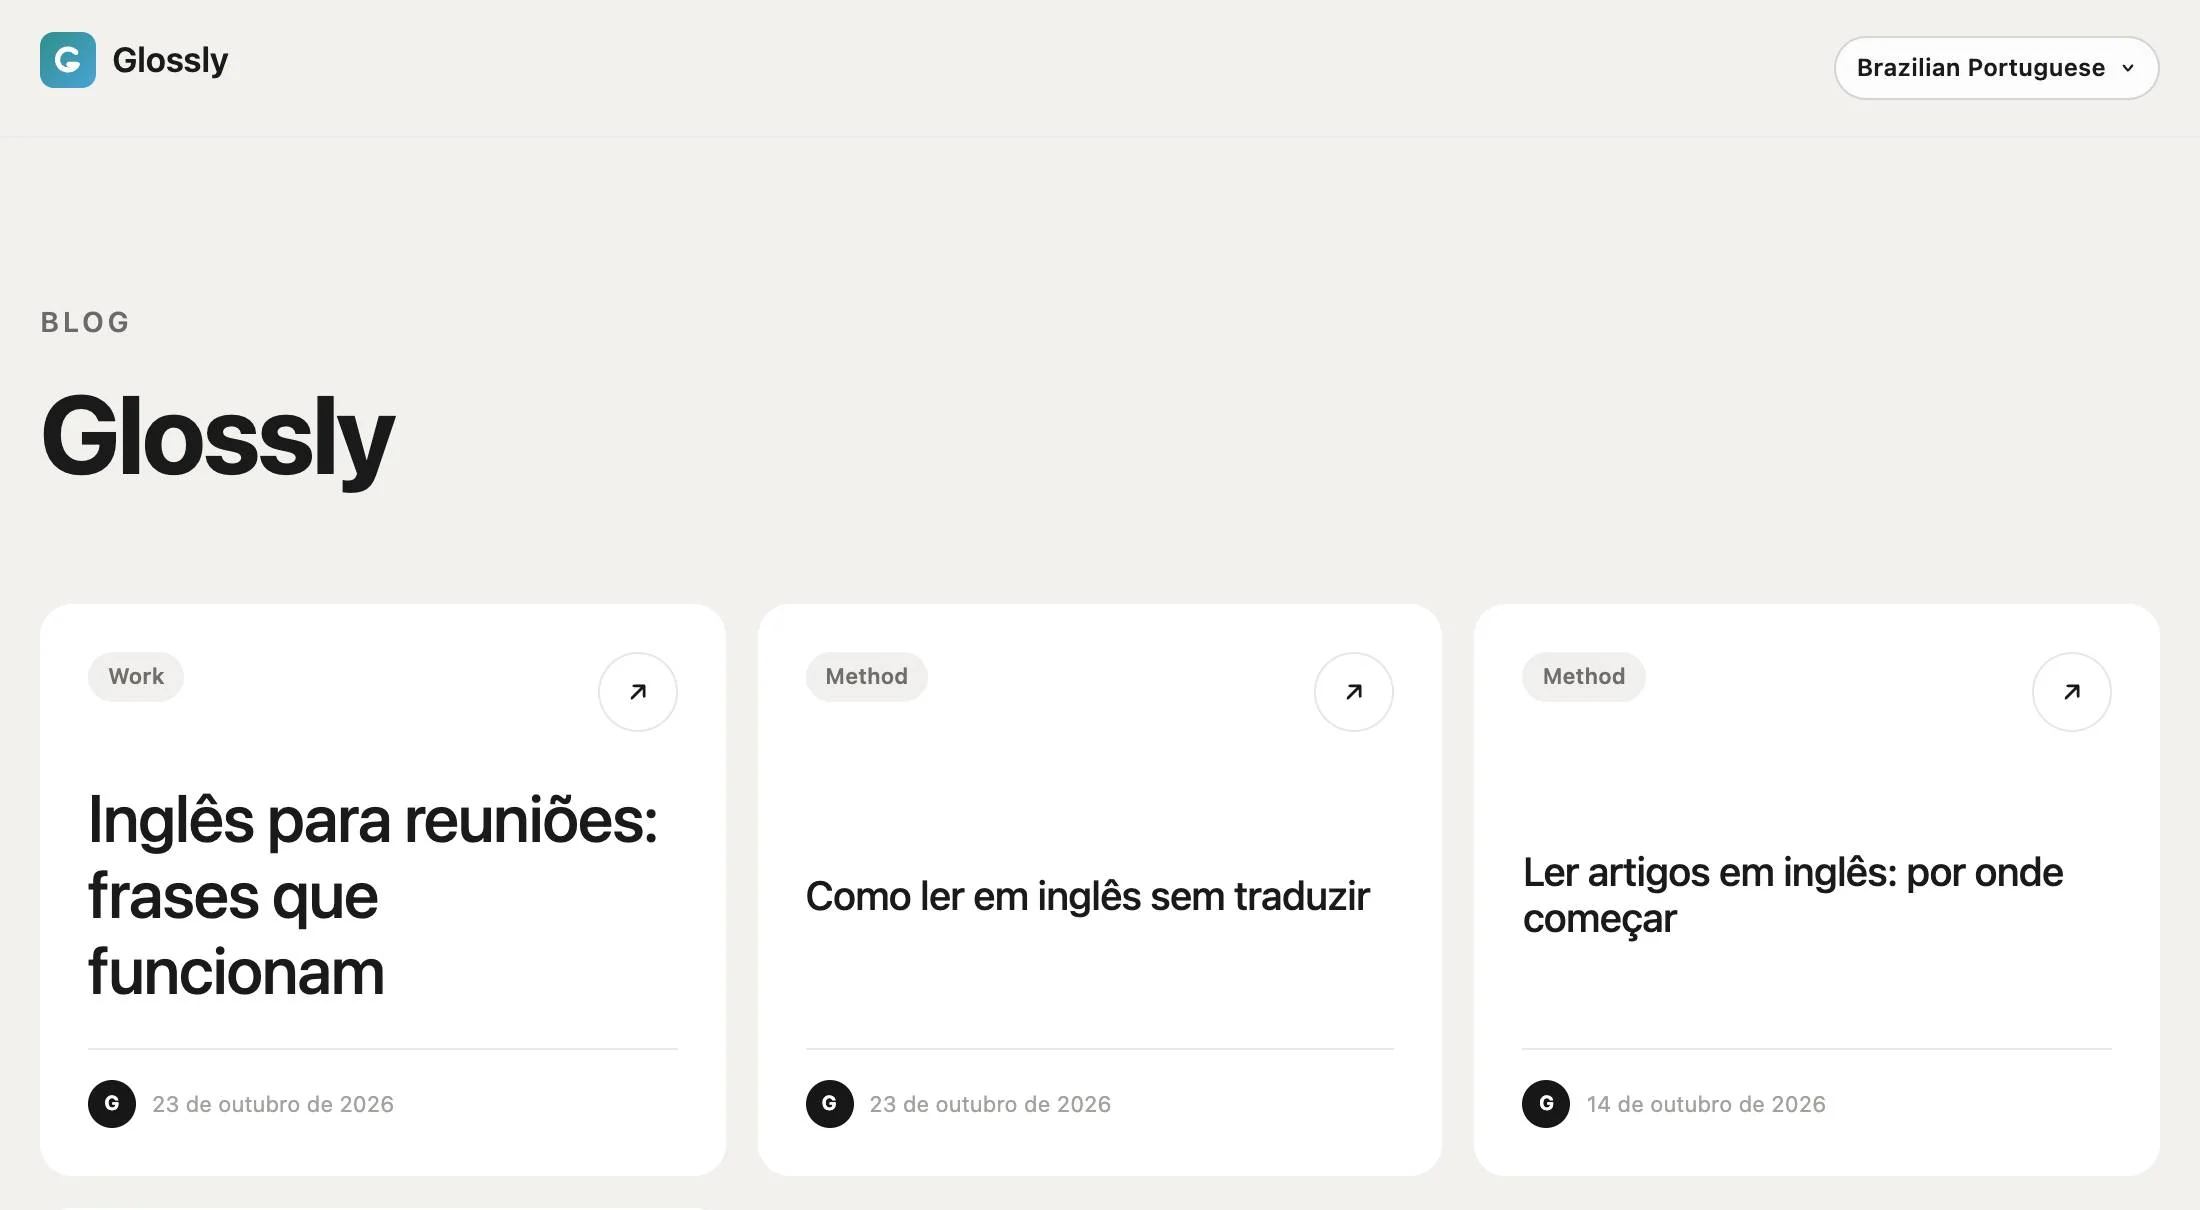
blog.glossly.example/pt/blog
The hosted blog for the sample product Glossly: its logo and name, a language switcher, and article cards in Brazilian Portuguese.

Rendered by the product’s own blog template. Glossly is a sample product.

Hosting works on a subdomain. Serving under www.yourdomain.com/blog needs a reverse proxy on your main site.

Search Console

It doesn’t grade itself. It asks Google.

Sign in with Google once. From then on the team submits what it publishes, reads what Google measured, and judges its own work by those numbers, not by how the draft felt.

  1. 01

    Connect once

    One Google sign-in. The team adds your blog as a Search Console property and submits the sitemap after every publish. The property lives in your own account.

  2. 02

    Google’s numbers, every day

    It pulls clicks, impressions, click-through rate and average position, by query and by page, and waits out Google’s few-day delay. A day Google hasn’t finalised stays unknown, never zero.

  3. 03

    The numbers go back to work

    The Strategist and the Keyword Researcher read which queries already earn clicks. The Learning Agent scores each article against the target it set before writing, measured from that article’s own publish day.

Self-evolution engine

Pre-registered LearningThe self-evolution engine for AI agents

It writes down how it will be graded before it writes a word.

Pre-registered Learning fixes the scoring standard before the agent starts work, lets real Search Console results mark the outcome, and moves what an experience is worth only when later work actually used it. The agent learns from what happened, not from its own opinion of itself.

View the mechanism
Pre-registered learning on one timelineIntent is written and frozen before the work. Experience is rewritten as evidence arrives and is scored against the frozen intent when the outcome returns. Utility stays empty until a later task adopts the experience, then moves by 20 percent toward each new score.IN SCIENCEhypothesis + standardrun the experimentcompare, reviewadjust the next runBEFOREDURINGAFTERLATER TASKSFROZEN01IntentWhat were we trying to achieve?Learning Agent writes it · frozen on hand-back02ExperienceWhat did the work teach us?Learning Agent · rewritten from evidence03UtilityHas it helped later work?Computed by code · no model writes itgoal · context · expectationhow it will be scoredlocked: nobody can change it from herecomparedeliveryreportfeedbackreportpublicationeach new piece of evidence rewrites the findingsoutcomescored against the frozen standardreward 0 to 1, or unknownempty until someone uses ita later taskadopts it, with a receiptits score flows backutility moves 20% of the waytoward each new score
  1. 01 IntentWritten and frozen before the work starts. The goal, the conditions, and exactly how it will be scored.
  2. 02 ExperienceRewritten each time the system records new evidence. Scored against the frozen standard when the result returns.
  3. 03 UtilityEmpty until a later task adopts the experience. Then it moves, slowly, toward each new score.

Borrowed from science: state the hypothesis and the standard first, run the experiment, then compare. The result is never allowed to change what counted as success.

One practice, start to finish

Each phase leaves something you can read.

BeforeThe standard

It fixes the exam first.

The Learning Agent writes how this work will be scored: what to measure, over how long, with what formula, and when the answer counts as unknowable. Then it hands the page back and the page locks.

Evaluation agreement · v1frozen
Objective
Clicks on work-context guides
Data
Search Console clicks and impressions
Window
28 days from each article’s publish day
Score
min(clicks ÷ target, 1)
Unknowable when
Any day of the window is missing
Adoption receipt

Used “Titles answer the search question”. It changed all three titles. Unsure: only tested on guides.

DuringThe record

The system keeps the evidence.

Specialists never know learning exists. Database triggers log each formal event as it happens, and the Learning Agent rewrites its findings from that ledger, citing every line it relies on.

Evidence ledgerrecorded by the system
  • reportWriter finished three draftsOct 23
  • feedbackReviewer sent article 2 backOct 24
  • reportWriter resubmitted article 2Oct 25
  • publicationThree articles went liveOct 26
Finding · adjustment

Article 2’s title changed because the reviewer said it didn’t answer the search. Cites evidence 2 and 3.

AfterThe result

Google marks it. Code does the sums.

Weeks later the real numbers arrive. A numeric score comes from the frozen formula, calculated by code, and the model cannot fill it in. If the data is not all there, the score stays unknown.

Outcomept-BR · 3 articles

0.71

RewardAll three windows complete. Computed by code from Search Console.

unknown

RewardOne window is still open. Never filled in with zero.

What an experience is worth

A score only moves where it was used.

  1. Read is not used.Only an experience the Leader adopted, with a receipt written before the work was handed out, can ever be scored.
  2. Only like for like.A result counts only when its scoring basis matches the one the experience was built on.
  3. One bad day doesn’t flip it.Each new score pulls the utility 20% of the way. It takes several poor results in a row to move it far.
  4. Unknown doesn’t count.A missing or incomplete result is skipped, not scored as zero.
An experience that scored 0.8, then 0.3, then 0.6 ends at a utility of 0.680.00.51.0Titles answer the search question · v3task scoreutilityutility 0.80Task A · first useutility 0.70score 0.3Task Butility 0.68score 0.6Task C20% of the gap

A utility is not the score of the work that created it. It is what the experience earned in the work that came after.

Who decides what

The model reads. The code rules.

The model decides what needs understanding

  • Whether a past experience fits this task
  • Whether two pieces of work are really the same kind
  • What the evidence says: what changed, what was delivered, what is still unknown
  • Whether to use an experience at all. Only the Leader does

The code decides what can’t be bent

  • The standard, locked before the work starts
  • Which evidence exists, and who wrote it
  • The score, from the frozen formula
  • Whose score lands on which experience
  • Unknown stays unknown

Only the Leader ever touches learning. Every specialist does its job without knowing it is being learned from, so the record stays in one place and stays honest.

Start it tonight.

Then walk away. Check back to see what it published.

View the source on GitHub →
Node 22.18+ · runs locally first
$ git clone https://github.com/Agencize-ai-open-source/growth-harness.git
$ cd growth-harness && npm ci
$ npm run setup -- --local
$ npm run dev
# add a model key in .dev.vars, then give the Leader a goal